English versions of selected startit.rs articles. Each section below is one article; the yellow box at the top of every section links to the Serbian original, and the Serbian original links back here.
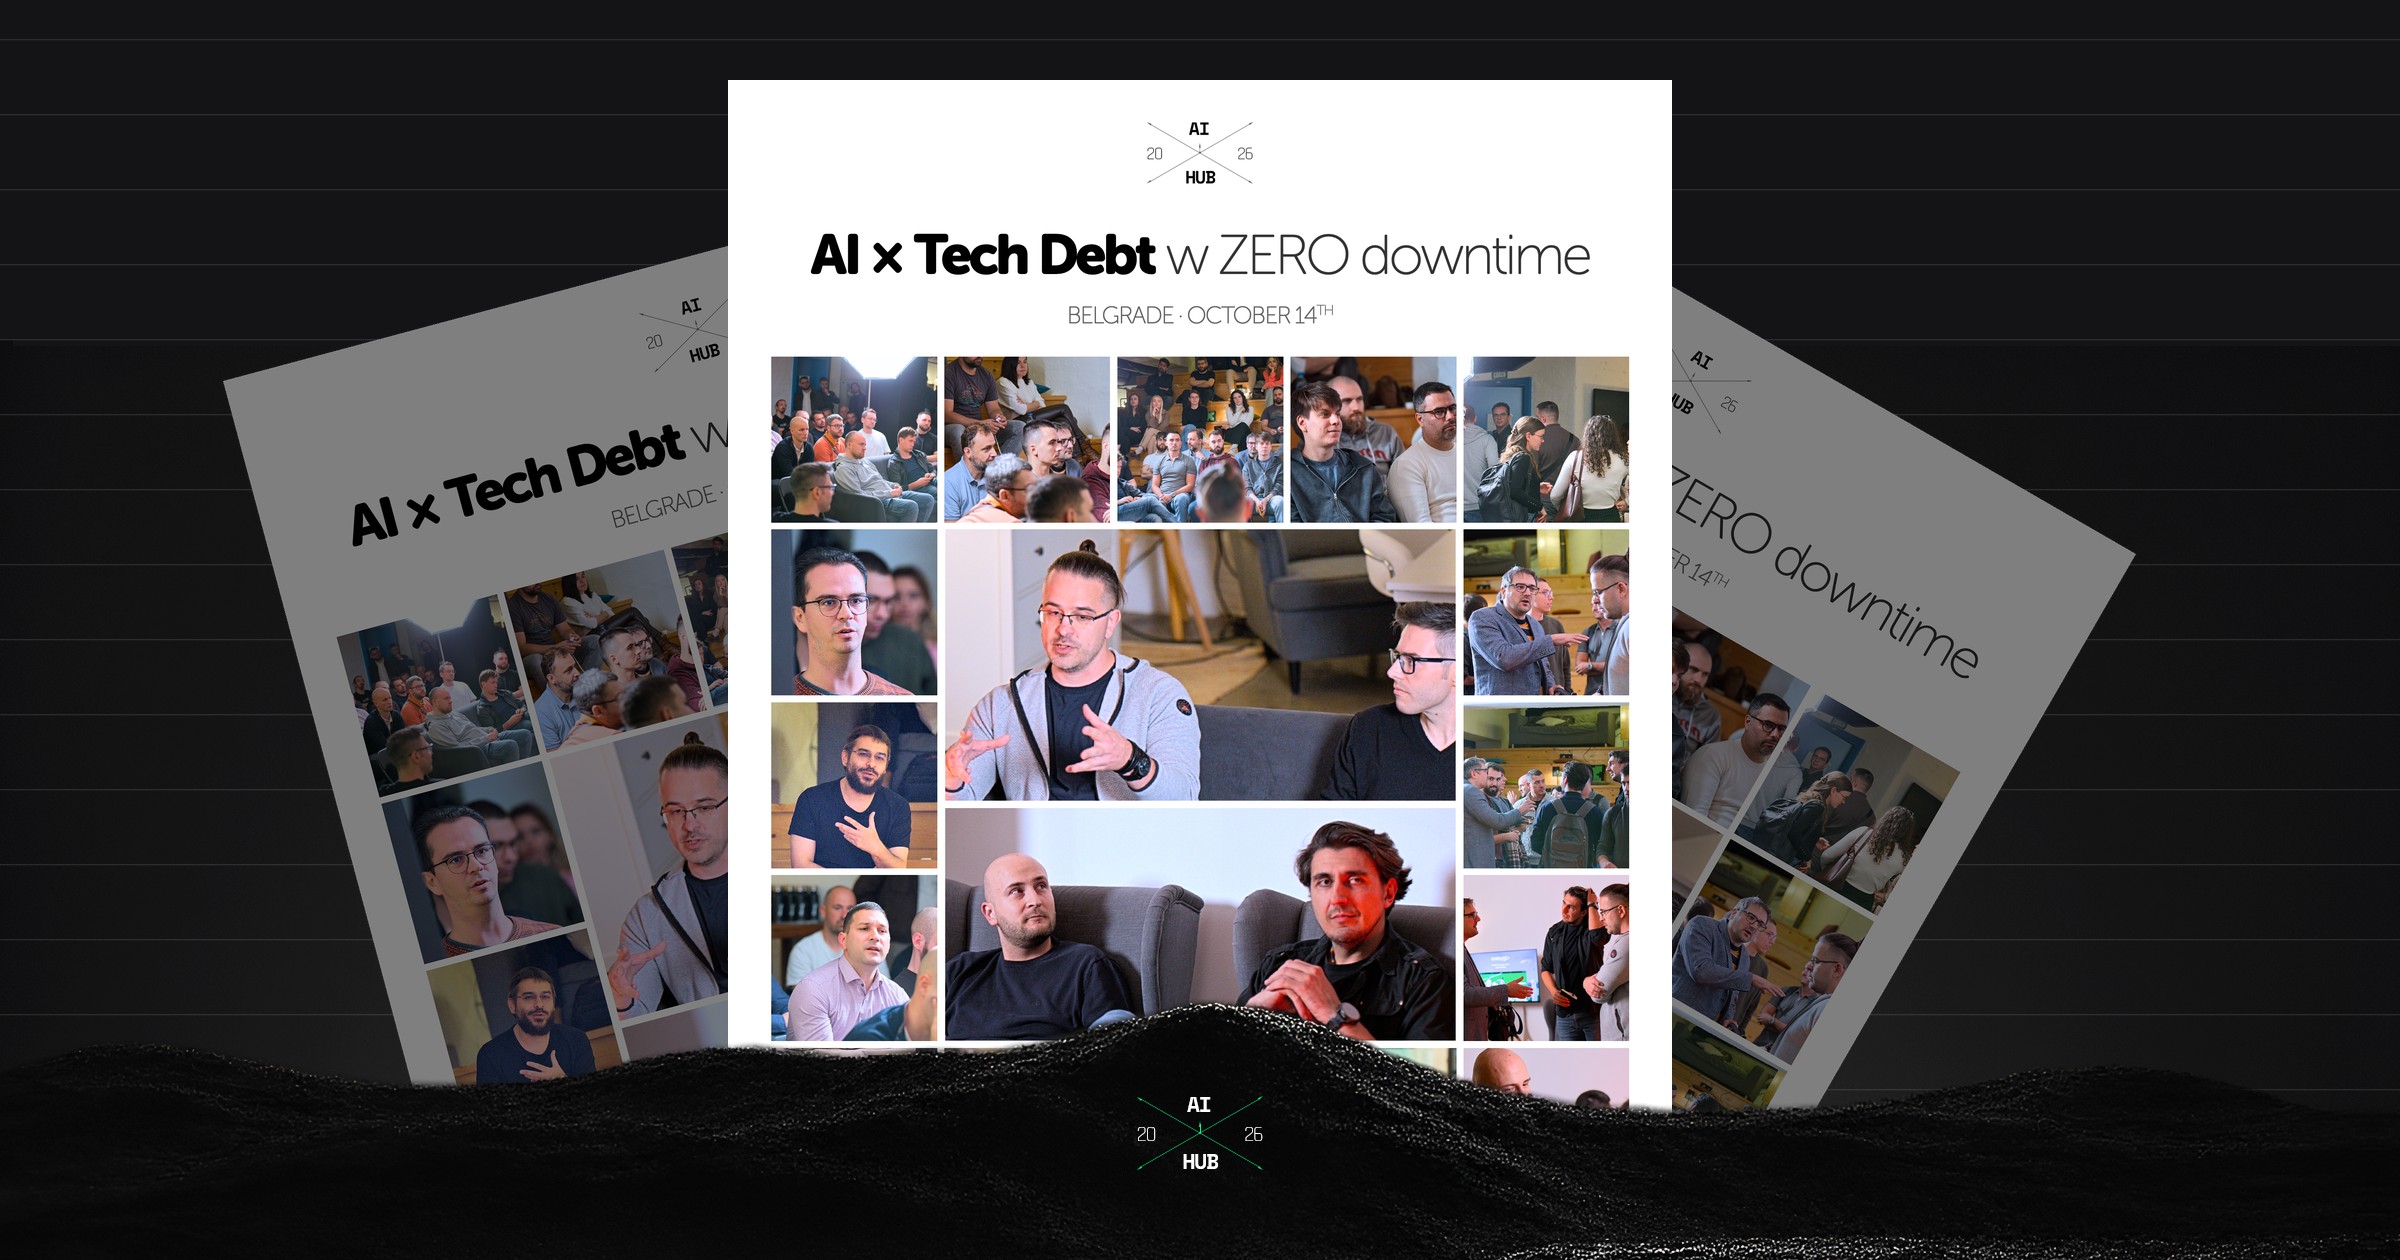
At the fortieth AI Hub meetup, three engineers from Easygo's Belgrade office told us how they did it at KICK, and where AI helped them finish work originally estimated at nine to twelve months in two to three.
Miroslav Lazović, principal engineer, talked about migrating the payment system; Igor Stojadinović, staff engineer, about the user system; and Miloš Zlatković, software engineer, about building a new notification system.
Through their examples we discussed when tech debt starts to hold back growth, how AI changes the math of paying it off, and what it takes for accelerated implementation to reliably reach users.
To understand the complexity of an undertaking like this, a few metrics help.
During the Stream Fighters 4 broadcast on October 18, 2025, KICK reached 4.6 million concurrent viewers. The chat receives more than 46 million messages a day, about 530 every second. In 2025, 4.5 billion hours of content were watched on the platform, 131 percent more than a year earlier.
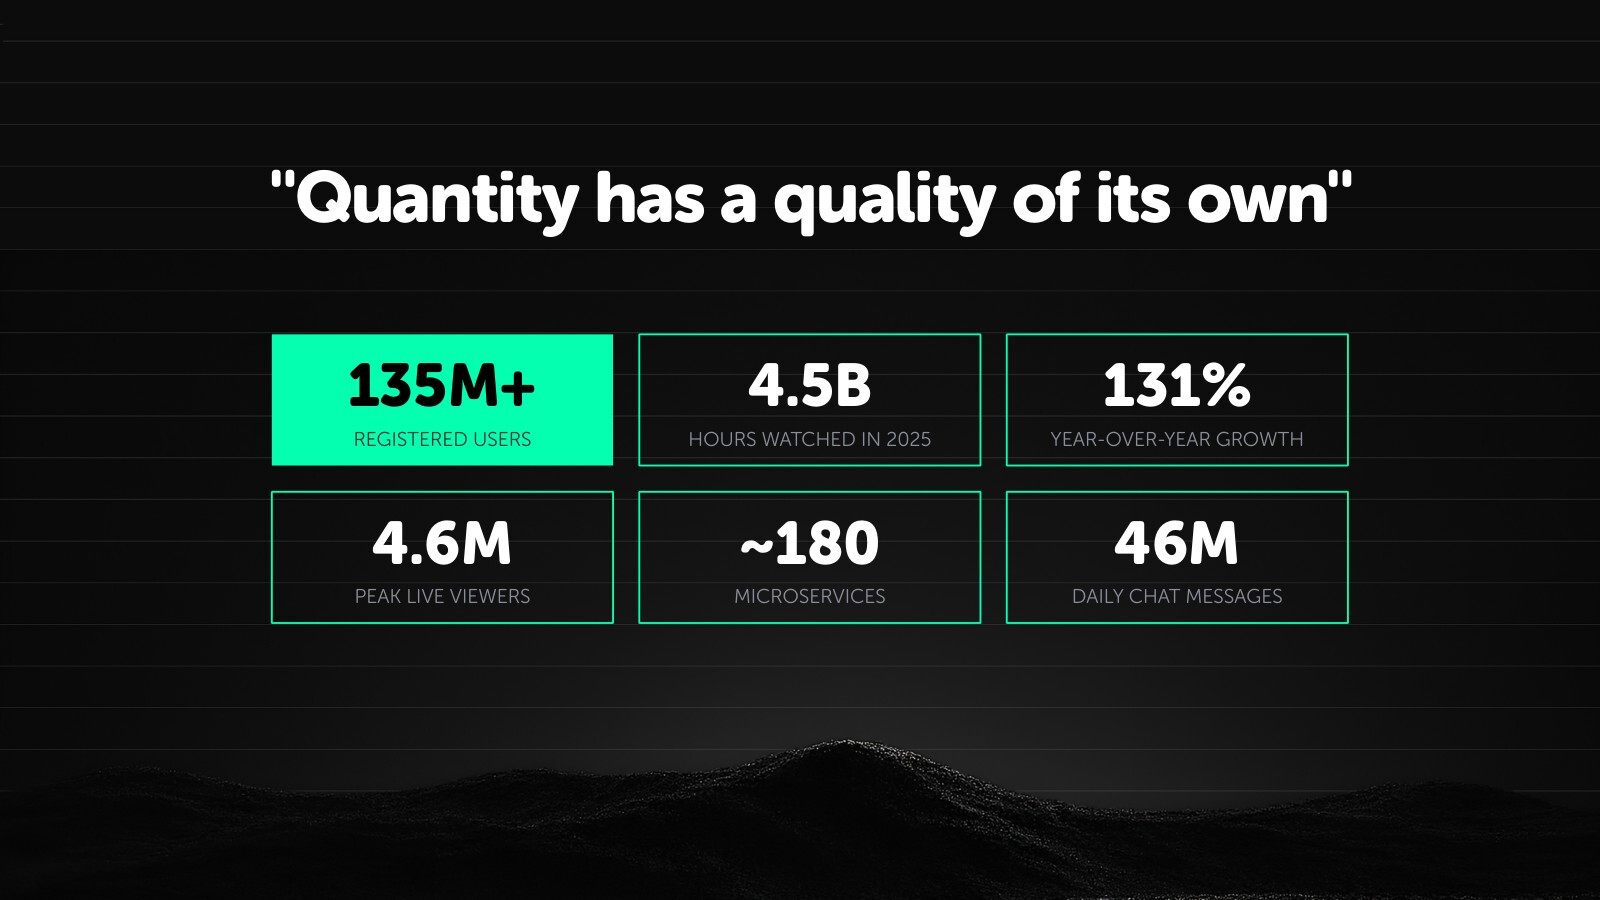
That growth is carried by a team of just under 60 engineers globally; for comparison, Twitch, the leader in this category, has around 600.
Easygo's Belgrade office is the company's only engineering office outside Australia, and is home to about a third of the global engineering team. Among the things it is responsible for are the very foundations of the platform: user accounts, payments and the notifications that bring the audience to a stream.
The team behind this project has a lot of experience. Miroslav has spent almost two decades working on critical systems, with the incidents and on-call duty that kind of work involves. Igor has been in the industry almost as long, and for the last seven years has focused on organizing software around business domains. Miloš has about ten years of experience and an interest in large systems with many users.
That experience showed throughout the conversation: from deciding what to change at all, to the question of how to recover when something goes wrong.
KICK started as a PHP monolith. As the platform grew, Go microservices were built around it, with the idea that they would gradually take over its work.
Over time the monolith kept getting new features, and so did the Go services, and the gap between them widened. Meanwhile, the data was split between Postgres on AWS and MySQL databases at PlanetScale.
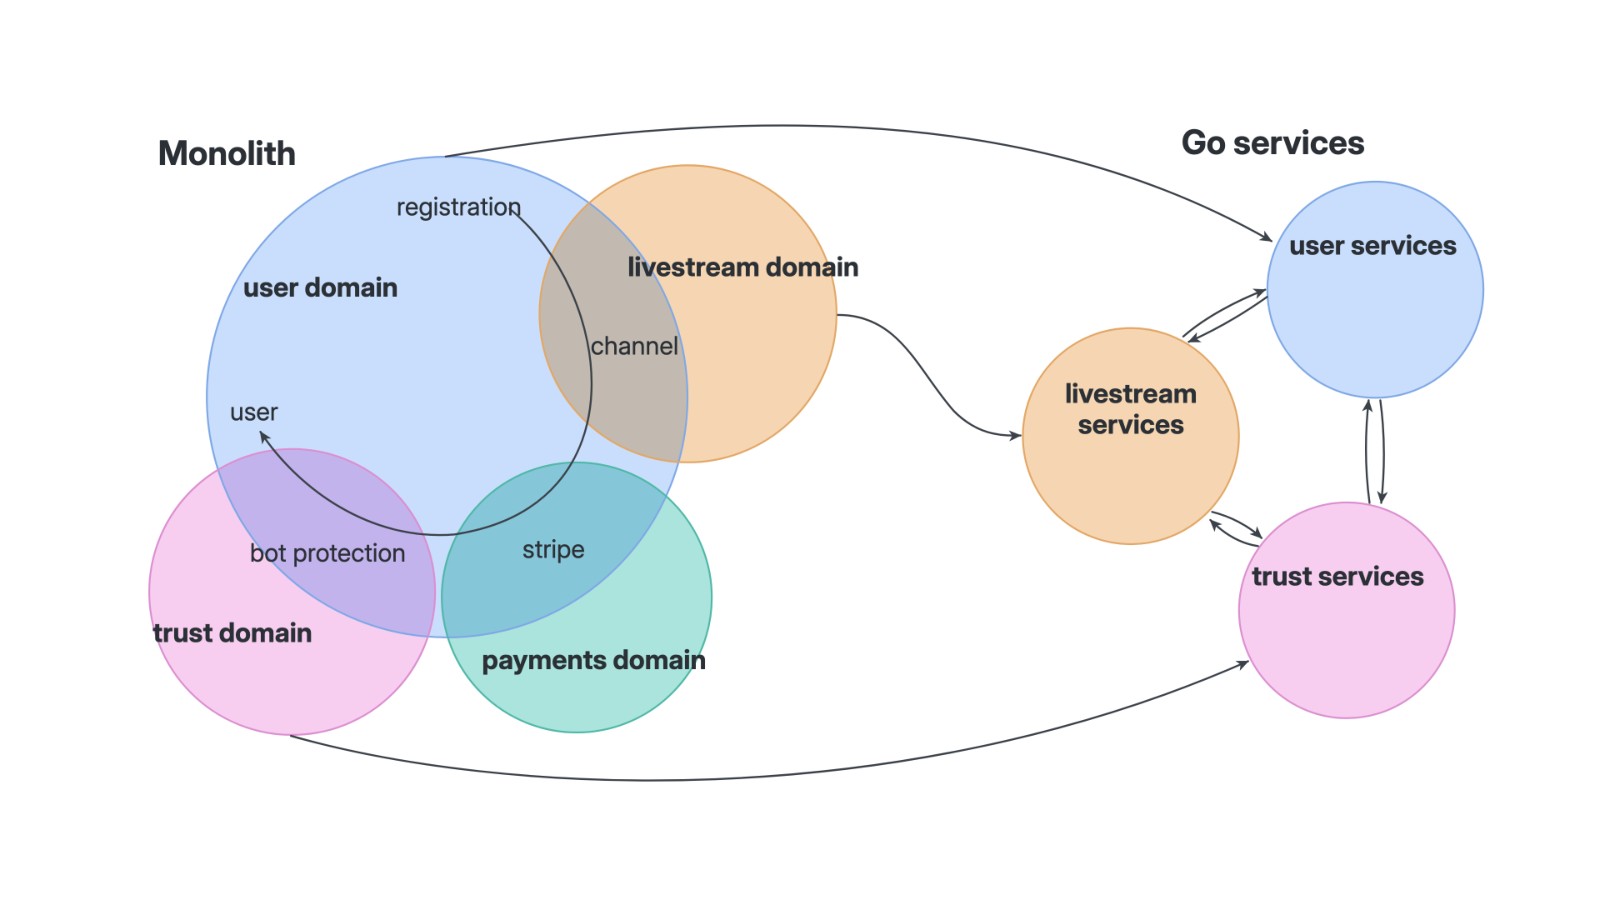
The consequences became more and more visible. Miroslav singled out the PayPal integration: work estimated at about a month took almost a whole quarter, because along the way the team had to rework parts of the existing system.
For a platform growing in new markets, a locally available payment method can be the reason a user tries it at all. When such an integration takes three times longer than expected, tech debt gets a very concrete business price in the form of slower revenue growth.
Growth also exposed the limits of external services. Igor explained that the old sign-up triggered several processes at once: creating the user account, the channel, the Stripe account, and registering with the bot detection system.
At one point the number of new users became so large that Stripe started rate-limiting requests. The team had to find a way to process everything needed without sign-up waiting on an external service's throughput.
With notifications, Miloš's challenge was for the system to determine and notify a large number of users (up to five million) within a few minutes that a streamer had gone live, and to do so through services that have their own quotas. A notification that arrives half an hour late dramatically hurts the user experience.
Everything pointed to the same problem: further growth required a serious change to the foundations.
A big migration carries risk and takes time that could go to new features. The user, meanwhile, rationally from their perspective, expects only that the product keeps working.
Miroslav said the conversation with management went fairly smoothly, partly thanks to the company culture and partly thanks to how the team presented the work.
The plan was split into phases, each delivering a concrete result: more speed, security, privacy or room for further development. A common mistake when presenting big initiatives like this is to treat the whole job as one long, relatively opaque block, after which the system will be in better shape.
The situation is drastically different, however, if the work is presented as a series of smaller pieces (limited to a month or less), each bringing a clear benefit to the end user, improving system performance, or contributing to a concrete business goal. The first phase of the user migration, for example, cut sign-up time in half.
Igor recommended framing the conversation around outcomes: what the company gets during those three months and what each stage makes possible. That way the value becomes visible even before the whole project is finished.
Management's requirement was that the core experience of using the platform stay the same. Watching, streaming and chat had to keep working, while for payments a temporary pause of a few hours was agreed. All in all, very challenging, to put it mildly.
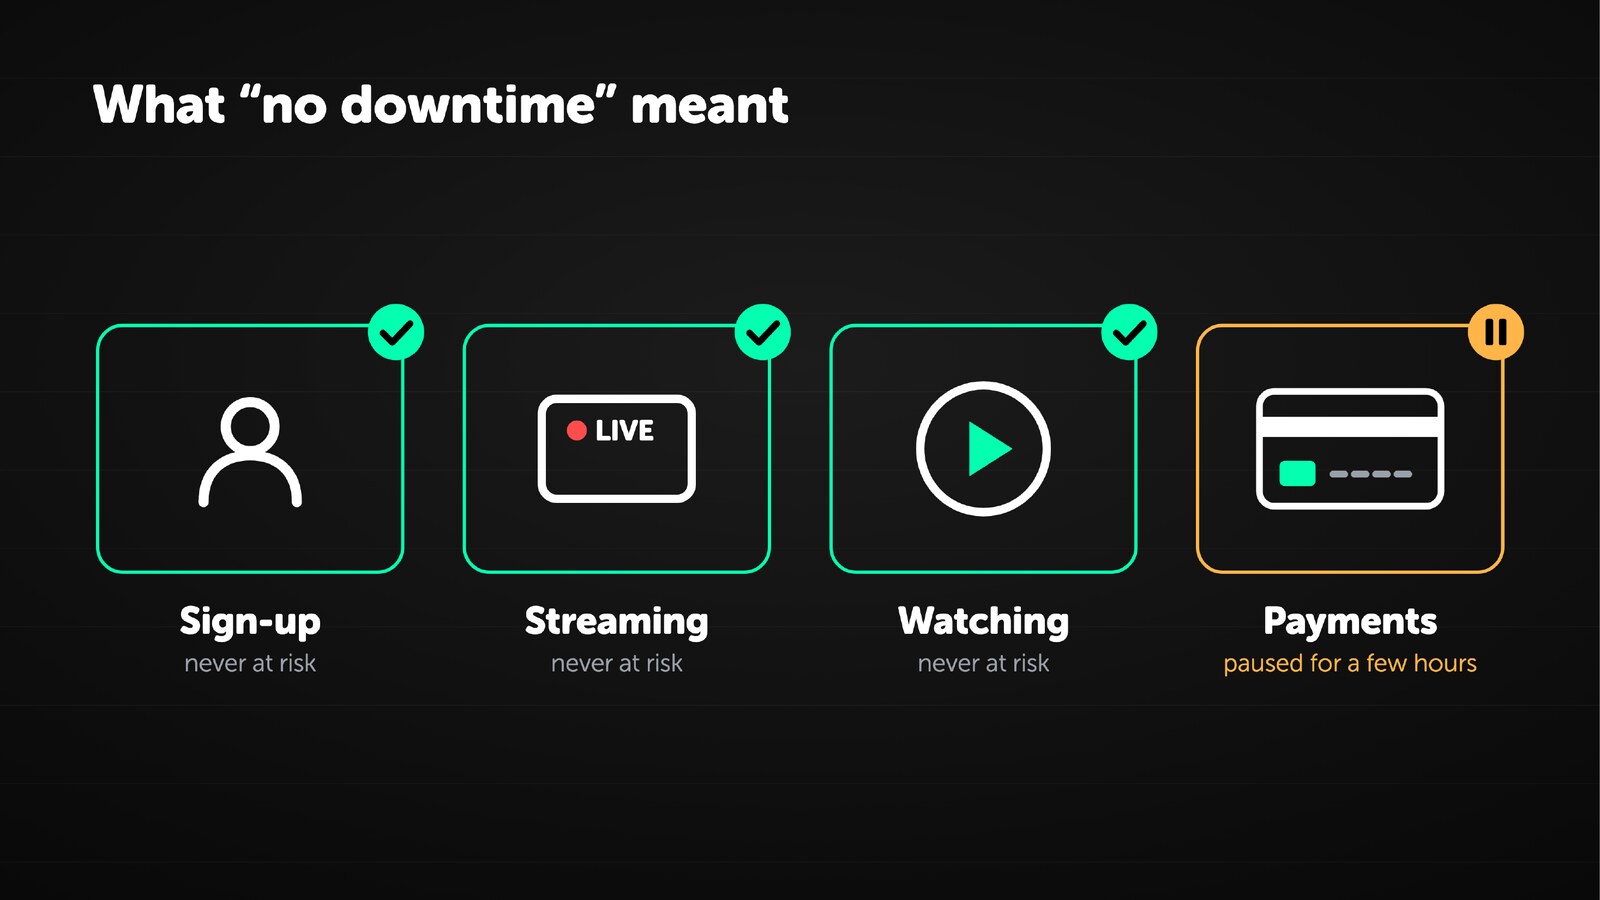
With payments the stakes are especially high. Miroslav reminded us that even a short-lived problem can become a reputational incident that lasts much longer than the outage itself. That responsibility determined how carefully the transition had to be planned.
Before changing the system, the team had to understand everything that was in it.
In its first years KICK was developed quickly by the team of the time, decisions were made on the fly, and some of the people who made them were no longer at the company. The code stayed, but the explanations were not always with it.
This is where Igor ran an experiment with Claude Code. The analysis took almost four hours, spun up additional agents and produced twenty detailed documents on the system's behavior and the requirements the new platform has to support.
Asked whether this saved him a month of manual work, he estimated the saving may have been even bigger. The team might never have reached some of the details at all.
That was one of the most concrete examples of the change AI brings: a large part of the research becomes available faster, so the team can check assumptions and plan next steps earlier.
Even so, documenting existing behavior is not the same as deciding it is correct. Something that looks like a bug may be covering a historical business case. The team had to judge what to keep, what to fix and what to remove.
At that point the three projects went different ways.
With payments, the priority was consistency. Miroslav's team carried over the existing business logic, including known imperfections, and left fixes for the period after it was established that the new system works identically to the old one.
The reason is practical: if you move data, change programming language and rewrite business rules at the same time, it is harder to find the cause of any discrepancy.
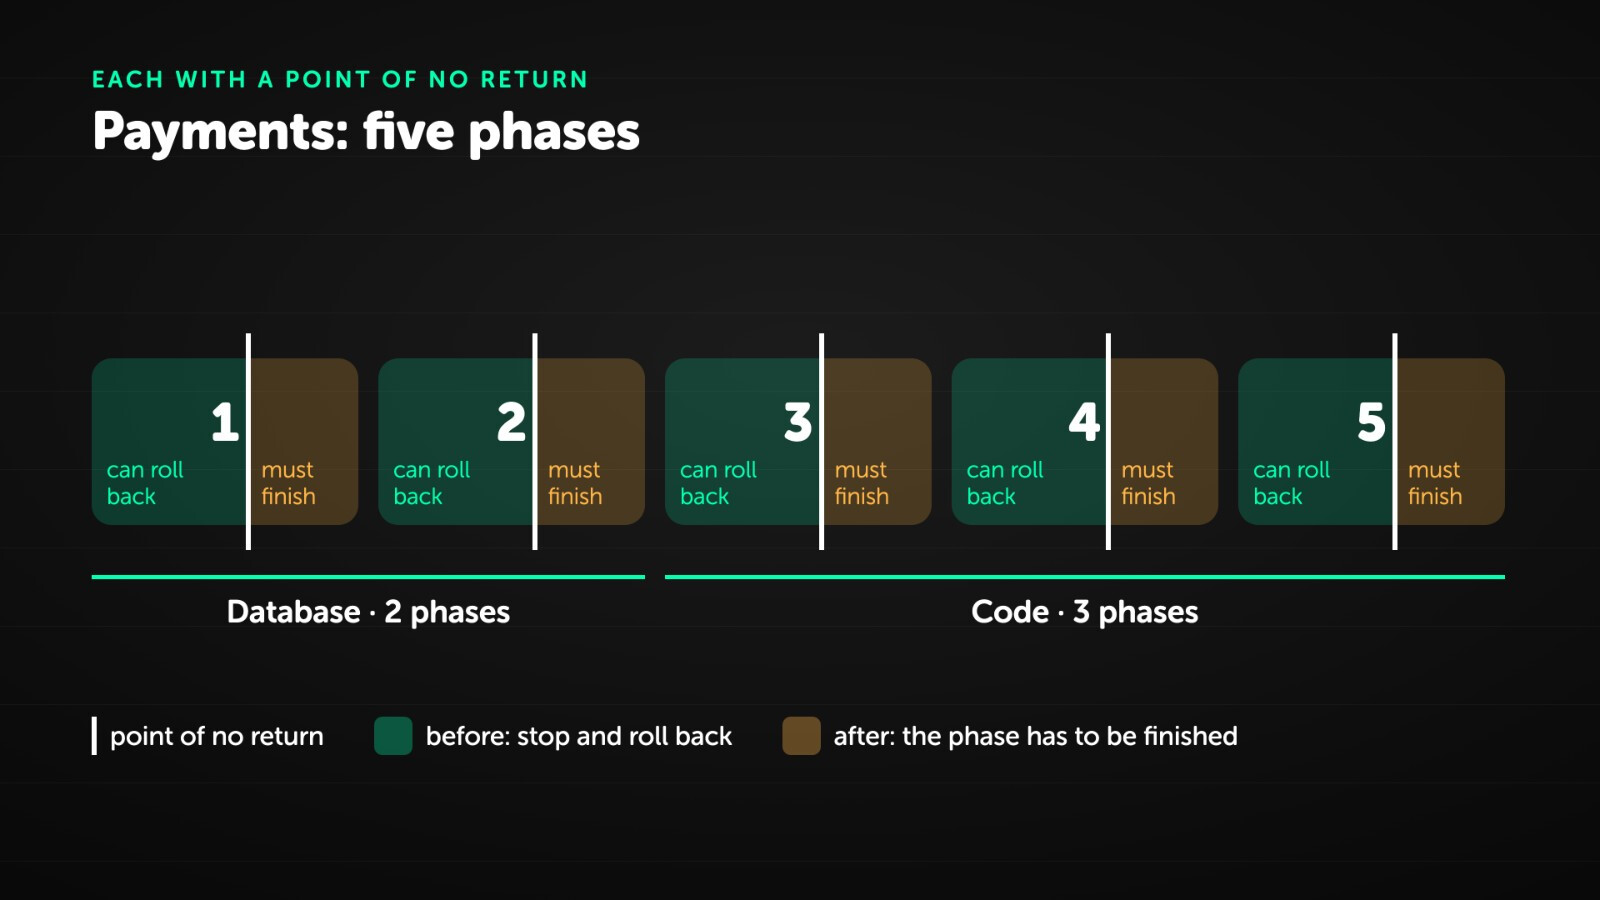
The plan had five phases: two for the data and three for the code, from simpler to more complex functionality. AI helped check the order and find blind spots before they became production problems.
With users, Igor's team could also change the sign-up flow. In the new system the account is created within the user domain, and then an event is published. Other parts of the platform react to it and do their work, without sign-up having to directly manage each of them.
This separated processes whose dependencies used to slow the user down. At the same time, the old and the new system had to coexist without the data diverging.
Miloš's team built notifications from scratch. The old system had tightly coupled delivery channels, so a stall in one could drag down the others. The team first defined principles, the target architecture and constraints, and then used AI to break them down into tasks ready for implementation.
Although the tools were similar, the decisions depended on the nature of each system. Knowledge of the product and the engineers' experience remained key to setting the boundaries of the change.
They also openly shared some of the problems that came up along the way.
During the migration, another part of the platform started sending six to seven times more traffic to payments. The system worked with raw data and demanding calculations, so the new load created a bottleneck in the middle of already complex work.
At certain moments they reached the largest available database instance. Adding more capacity was no longer enough.
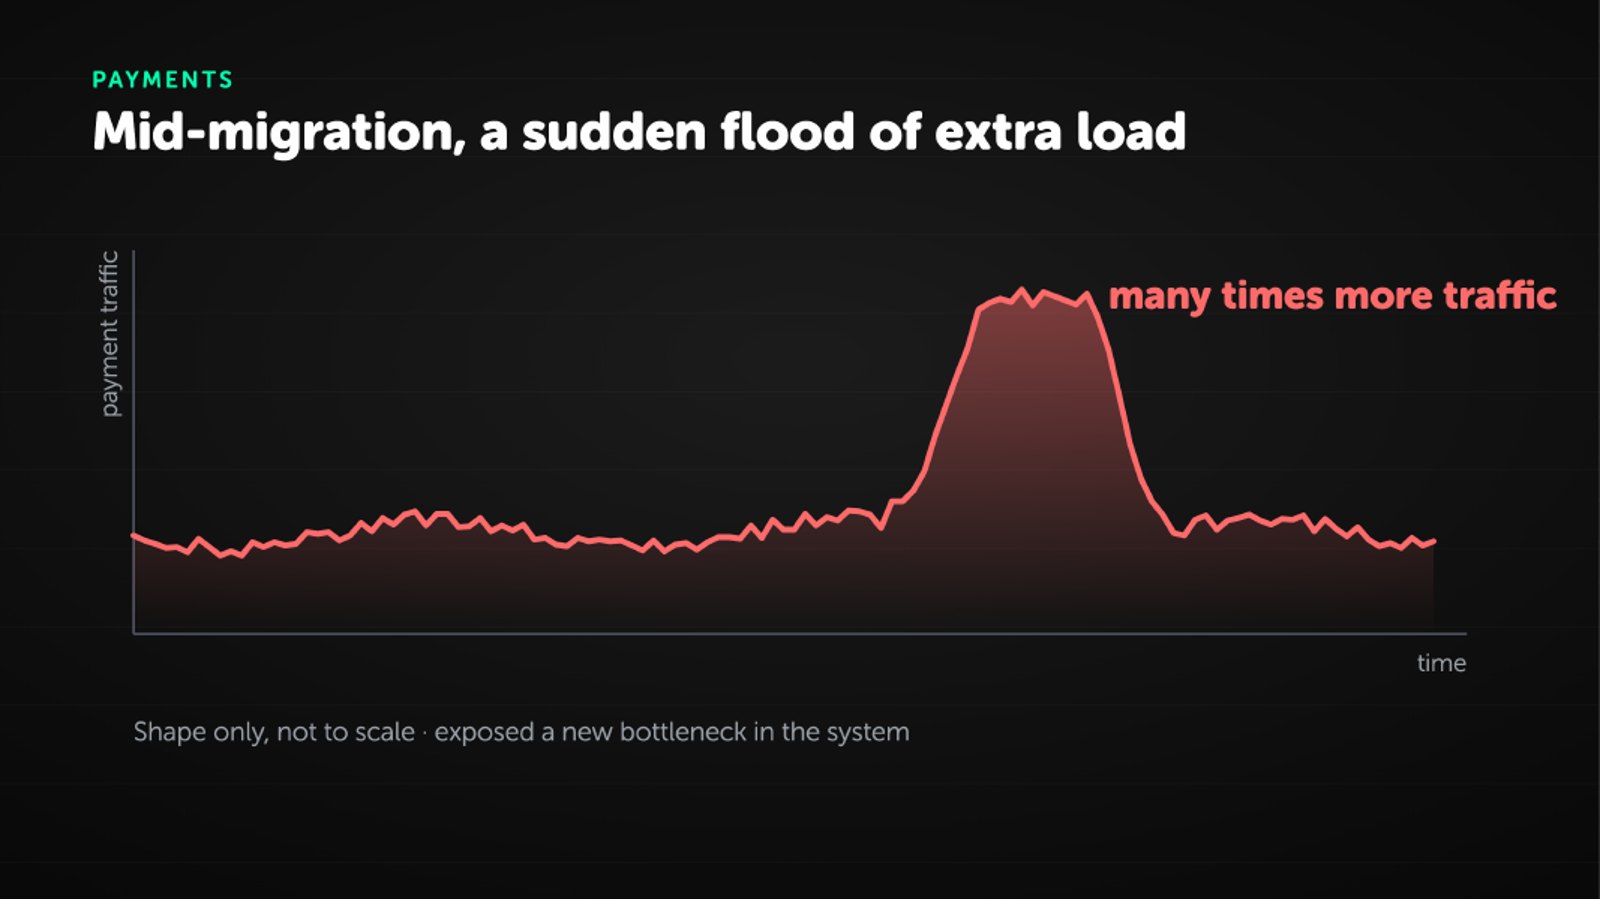
So between the fourth and fifth phase the team inserted an extra step: a new dedicated application that stores pre-processed data and serves the systems that need it. It was finished in about a week.
Examples like this showed why so much attention was paid to verification during the evening. Audience questions kept coming back to how the team keeps control over changes and over the agents' work.
For payments they combined tests of critical flows, comparison of the old and new system's responses, manual testing and production monitoring. After a problem with missing indexes during the database move, every subsequent stage got a detailed runbook: the order of steps, communication and concrete indicators to watch.
For a week, notifications processed real traffic without sending actual notifications. Only after that check did the new system gradually take over delivery.
The final payments test was simple: during the agreed pause, production transactions were enabled only for accounts with an Easygo email. The team tested the system with its own money.
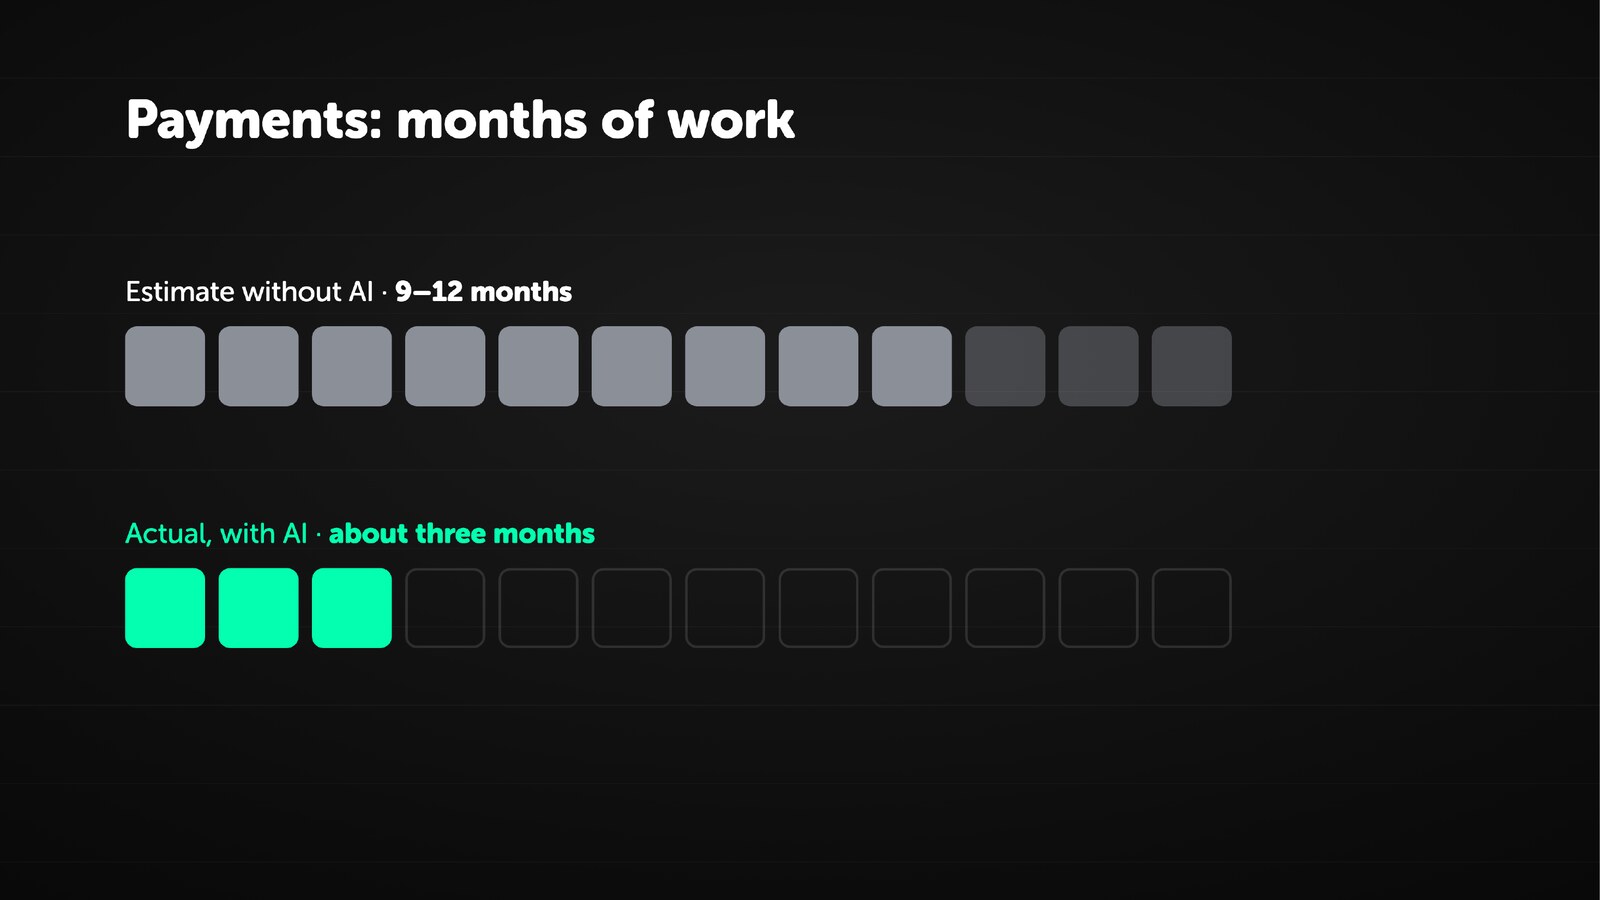
The payment system migration was finished in two to three months, against an initial estimate of nine to twelve, including unplanned interventions and moving terabytes of data.
The user system, originally estimated at ten to twelve months, was migrated between March and September. Igor described how quiet the switch was: they released the new system on a Wednesday, and announced that the migration was finished only the following Wednesday.
Notifications were built in about three months. According to the measurement they showed at the meetup, notifications now arrive 2.1 times faster, and the system opened room for new features.
We also talked about what it cost. For payments, the estimated cost of AI tools was 15–20 thousand dollars for analysis and code, plus about 10 thousand more for validation and follow-up improvements. For notifications, Miloš's estimate was 10–12 thousand dollars.
Those are tool costs, on top of the work of the team that led the projects. Easygo let its engineers use them without a preset spending cap, with the understanding that faster delivery and the ability to develop the product sooner have business value.
The project also left behind documentation the team can use for future work. Miloš especially highlighted recording rejected ideas: alongside every important decision, it was also saved why other approaches were not chosen.
How much that matters became clear when he went on two weeks of paternity leave. Two colleagues with little prior context took over the project and continued without a hitch. The same knowledge makes it easier to work with colleagues in Melbourne, who are in a different time zone.
There were more questions than we managed to cover during the official part. The audience was interested in model choice, working with agents that head in the wrong direction, testing, and how much code the speakers still write themselves. The conversation continued after the program.
The same responsibility ran through the different approaches: the team has to understand the system it is changing and know how it will verify the result.
That is exactly what gave weight to the numbers we heard. Behind the acceleration stood the experience of Easygo's engineers, the company's support and carefully run work on KICK's key systems.
For the user, success can look quite simple: sign-up is faster, the notification arrives on time, the subscription works. Underneath are migrated data, replaced services and removed obstacles to the next phase of growth.
Industry trends in general, and this team's experience in particular, give good reason to reopen estimates of big technical projects that have been waiting a long time. AI has changed how quickly they can be researched, built and verified. At the meetup we heard what that looks like when the opportunity is used by a team that knows what result it wants to achieve.
You can find upcoming events and sign-ups on the AI Hub page, and the next one is the second part of this very story — join us on November 4.
In a classic digital product, the data team sees the user from the moment they open the app. Everything before that, where they were, what they used and why they came at all, is as a rule an assumption or a survey.
The gap is not small: some of the most expensive questions in a product, why someone comes and why they leave for a competitor, fall precisely into that invisible part, so companies cover them with estimates and market research.
For most products that is the only possible way, because other people's data is not theirs.
Solflare, the Serbian-Croatian fintech company behind the Solflare Wallet, used by more than four million monthly active users, works in a system where transparency is built into the infrastructure itself. Every transaction on the Solana blockchain is public, so the activity history of any wallet can be traced.
That history exists before the user installs their app, and it continues afterwards.
We asked Mihael Alapić, Data Lead at Solflare, how that changes the job of a data team. A year ago the team was just him; today there are six of them, and they are looking for two more.
All transactions that happen are visible on the blockchain.
That means that for a given user's wallet we can see the entire transaction history, regardless of whether it was made in Solflare or outside it.
If some user account moves to our competition and starts using their wallet, we can use that information too.
For users who install our app we can see whether they have had contact with crypto before, and use that for segmentation.
Combining product analytics sources with blockchain data really opens the door to a large number of different analyses.
— Mihael Alapić, Data Lead at Solflare
Segmentation here means dividing users into groups by behaviour, and product analytics is what the app itself records: screens, taps, steps. What is new is that those two things are being joined with a public ledger of transactions that belongs to no one.
This is also where one of the biggest engineering problems sits, one the data engineer job ad names itself: the pubkey from the blockchain, the device identifier from the app and the internal user ID need to be reliably linked so the team can understand the user journey across on-chain and product data.
The second change is the one every other data team sees as well: AI. Mihael describes it like this:
AI has changed the data team's job a lot.
Getting to reports and insights has become many times faster, mainly because far less time is spent on technical things that can be learned through practice, like writing code and SQL or learning a particular syntax.
What has stayed manual, and what now gets even more emphasis, is QA of the results, but also questioning the solutions that AI offers.
It is important to know how to communicate with AI, what can be trusted and what needs additional checking, but in general people's productivity has grown a lot.
What has not gone away is the most important part of the job: understanding what actually needs to be measured, whether the data is good and what to conclude from it.
The data engineer job ad says it directly: working with Claude Code is everyday practice there. The tools are otherwise standard for a modern data team, BigQuery, dbt, Python, PostHog, Dune, Metabase, Tableau; what is not standard is the amount and the kind of data that flows through them.
Raw transactions and app events become information through dbt: that is where they are cleaned, joined and modelled before they reach a report.
For an example of data overruling a decision the team would otherwise have made on instinct, Mihael reaches into Solflare itself.
One of the more significant examples was when data analysis showed us that a relatively small percentage of users, the so-called whales, meaning users with exceptionally high spending, generate a large share of our revenue.
That prompted us to give them much more attention, including setting up a team focused on their retention and satisfaction.
We launched VIP programmes, exclusive events and perks, and we actively involve them in product development through feedback on new features.
Insights like this sound fairly simple when retold this way, but they are actually the result of a combination of several different analyses and good knowledge of the product, so they are not exactly an everyday thing.
The data team has grown to six in a year. Asked what separates a good candidate from an excellent one in an interview today, Mihael says:
A good candidate stands out through knowledge, an excellent one through the speed with which they understand the problem, adapt and arrive at a quality solution.
With AI constantly raising the productivity baseline, the biggest difference today comes from curiosity, ownership, critical thinking and the ability to use new tools smartly rather than blindly.
Many of our readers who work with data do so in banks, insurance or e-commerce, not in crypto. For them Mihael has a direct answer:
Of course they are relevant for people outside the web3 world too. I hadn't had much contact with web3 before either.
What matters is that the person is generally good with data and interested in the industry they are entering.
What you additionally get here, working with large event datasets, complex distributed systems and a sense of ownership over the work from raw data to business decision, is very transferable outside web3 as well.
The job ads list both as desirable: experience from fintech, banking or insurance, and work with blockchain data.
Two positions are open, both for work from Belgrade, Novi Sad, Zagreb or remotely. Applications go through the ads: Senior Data Engineer and Senior Data Analyst.
When Marija Mladenović of Solflare walked us through the way her team designs with AI at one of our AI Hub meetups at the end of April, she closed with a caveat: what was giving her good results right then might not work at all a month later.
Four months on, we invited her back to measure together how much her practice had actually changed.
Asked to sum up the difference in a single sentence, she offered a scale: at one end, a process where everything is done by hand; at the other, one that AI drives. "If we were at 50-60%, we're at 80% now."
And when we asked how much faster the whole cycle is than in April, which was already dramatically faster thanks to AI, her estimate is at least 50%.
We started with the obvious topic: Figma, the main tool for most designers over the past decade or so.
Solflare's design team still keeps its design system, tokens and components in Figma, and that is where both designers and developers review everything before implementation. Marija is still in it every day, but for a different reason.
Not to design, but to keep an overview: to change a piece of copy, to look at a screen when we're checking something.
More to answer questions than to design.
Personally, I don't think Figma should be the source of truth for design.
The source of truth should be what's in the code, and that should then be visualized.
— Marija Mladenović, product designer at Solflare
Figma as a source of truth, she says, is a double-edged sword; her position is that the overview of what actually exists in the code should be generated, not drawn.
The decisive change is that Figma's MCP got a new version. In April, reading a file through MCP was so slow and burned so many tokens that for heuristic evaluation she preferred to send screenshots.
Today the same job, reading screens and pulling images out of the file, takes a few minutes instead of twenty to thirty. So what she used to do through a workaround in April she now does directly in the file.
Figma itself improved in another place too: there is finally a plugin that pushes a prototype from code straight into Figma, a tool she says she had been waiting a year for.
In April, Claude Design had existed for 12 days and came with a tight weekly limit; today it is a fully fledged product, and in her team, she says, it has become a habit. She uses it every day herself and has never once hit the limit.
Claude Design delivers a prototype in a couple of minutes. The time now goes into what surrounds it: writing the brief, laying out the key screens on the canvas the way you would in Figma, iterating through them, and only then developing the chosen part into a prototype.
For a whole feature that is a few hours of work. With an up-to-date design system, the output is "very similar" to their product, "almost identical in some situations".
For a competition inside the product she wanted a level-up animation, a job she would not even have attempted in Figma:
In a couple of iterations it packaged it perfectly, and I passed the file on to the developers.
That's something I wouldn't do in Figma, because I can't achieve it there.
I could, if I spent five days on it, which is exactly why that kind of work simply used to get skipped.
The furthest reach of automation is around the design system itself. All of it is packaged into a skill: a colleague of hers built it, and the whole team uses it.
You run it once: Claude reads the Figma file, recognizes what has changed in it and opens tasks in ClickUp, with the component version, a list of changes and the people who implement it tagged. That whole step is over in a minute.
And the biggest brake on skipping Figma completely?
Even now I can build everything through AI. It's just that what I get simply isn't consistent enough. That's what stops me from just handing it over to the developers.
She also adds a caveat of her own: she has not yet tested a full process without Figma on real features, so she cannot claim how it would hold up in a team with a complex design system.
She expects, though perhaps not quite by the end of the year, that they will build most things through AI, with the designer defining the product and setting the direction. She sees the process evolving toward a repository (say, GitHub) where design is on an equal footing with code.
Piece by piece, it already exists: a repository can already be imported into Figma and connected to Claude Code, and Storybook through MCP makes components readable for AI.
What is missing is for all of it to work as a single whole: to see visually what has been implemented and, from that, prompt a new page into existence.
At the end of June, Meta open-sourced Astryx, a design system that grew internally for eight years and powers more than 13,000 of Meta's apps, released explicitly as a system that both people and agents can work in. It is no coincidence that it came out in exactly this window.
Figma's plugin that connects Claude Code directly to Figma points the same way.
Her experience, moreover, is not an outlier. According to the State of Prototyping survey that UX Tools ran in spring 2026 on a sample of 1,478 designers, Figma still leads at 82.6%, with Claude right behind at 50.8%.
Of the ten tools designers use most each week, five are AI: Claude, ChatGPT, Claude Code, Figma Make and Gemini.
The AI in Design Report 2026, published in March, so still before our April event, pointed the same way: 91% of designers use AI in design at least weekly, and 75% daily.
AI Hub is supported by